New research, certified by the Transactions on Machine Learning Research journal, presents a comprehensive framework for how large language models can increasingly improve themselves.
Stony Brook, NY, September 22, 2026 - Human expertise and engineering have played a central role in shaping the large language models we use today. People wrote training examples, ranked model responses, corrected errors, and provided the knowledge and judgment needed to guide model development.
This human supervision has been crucial to improving LLM capabilities, but it comes with significant drawbacks. It is expensive, slow, difficult to scale, and ultimately bound by human knowledge and effort. At the same time, with the rise of AI agents, automated systems are becoming increasingly capable of generating data, providing feedback, evaluating outputs, and even coordinating complex workflows.
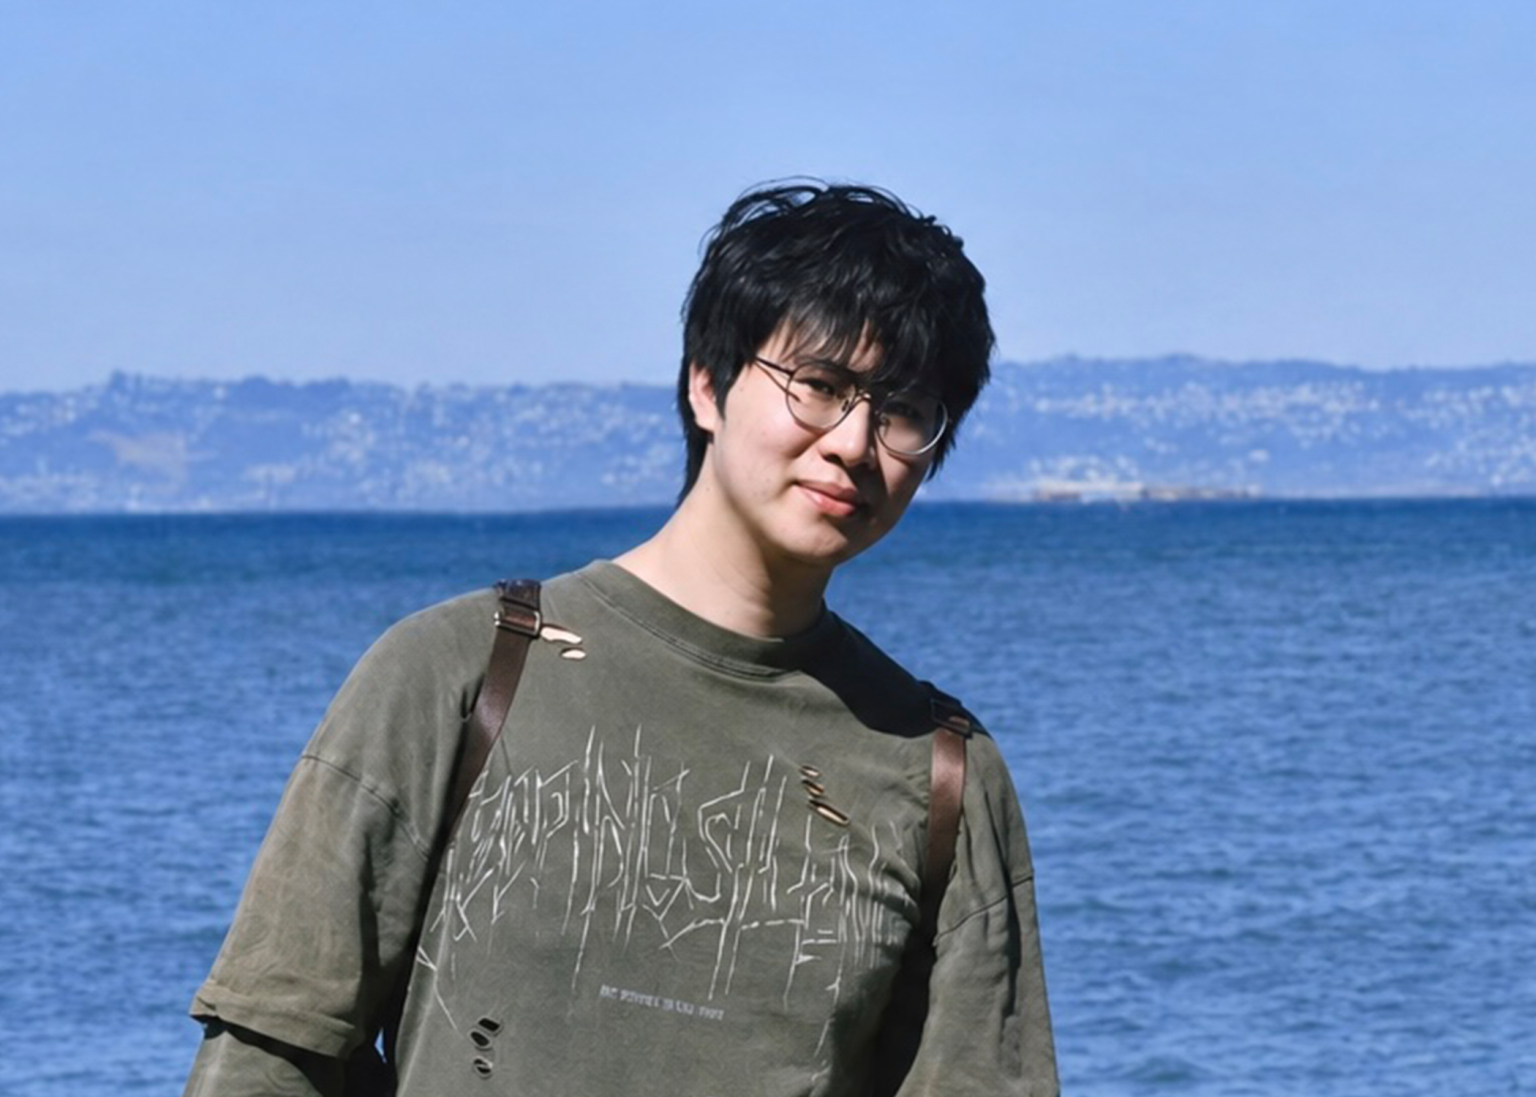
Stony Brook University’s Haoyan Yang, a Ph.D. student in Computer Science, and Jiawei (Joe) Zhou, assistant professor in the Departments of Applied Mathematics & Statistics and the Department of Computer Science, spent a year exploring this shift. What happens when human supervision becomes a bottleneck, and how can models increasingly take part in their improvement?
Their research “Self-Improvement of Large Language Models: A Technical Overview and Future Outlook” is the work of Zesearch NLP Lab and was recently accepted by the Transactions on Machine Learning Research (TMLR) — a prestigious machine learning journal — and recognized with the Survey Certification from TMLR, an award given to accepted papers that ‘not only meet the criteria for acceptance but also provide an exceptionally thorough or insightful survey of the topic or approach.’
Ph.D. students Solha Park, Huajian Zhang, and Yiyang Feng, and Master's students Mario Xerri and Sai Akhil Kogilathota also shared in the collaborative effort.
Yang, the paper’s lead author, addressed the project’s premise. “Five years ago, the mission was how we could train a smarter AI. Now the question is how AI can automatically learn to self-improve.” Self-improvement has emerged as a rapidly growing research direction, attracting increasing attention under related concepts and alternate names such as self-improving, self-evolving, self-adapting AI, auto research, and Recursive Super Intelligence (RSI). The team’s work distinguishes itself in how it lays out, or more precisely, doesn’t lay out, the scope. Most existing works concern individual agents — the scaffolding around a model, its memory, its tools, its environment. Yang and Zhou focused instead on the models beneath.
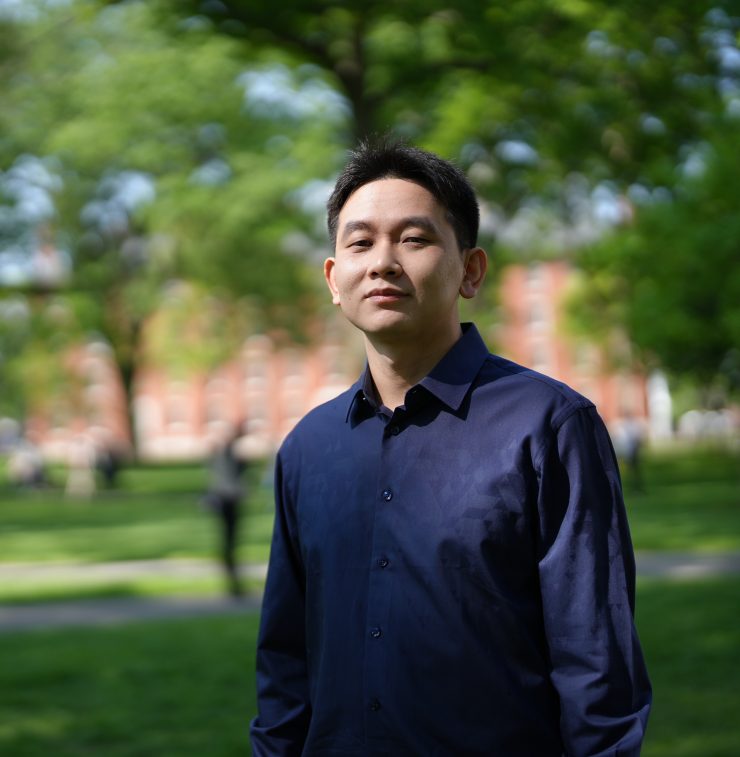
Zhou explained their approach. “Consider Google's AlphaEvolve. It’s an impressive system, but one that iteratively refines itself at the LLM's ‘Inference’ layer, which is a single stage of a longer process. The agent systems behind these iterations are, at the end of the day, driven by the models themselves.” Studying the model as an isolated object struck the team as equally unsatisfying as working with its individual layers. “So we considered studying more fundamental problems, like, how do we, from the ground up, build on already well-functioning models autonomously? And how do we improve them through the whole life cycle of the model development?”
The team decided to address the whole loop rather than any single link in it. They went over the four stages delegated to a standard AI model development cycle: data acquisition, in which the model gathers or generates its own raw learning material; data selection, wherein it judges what’s worth learning from; model optimization, where it distills data into model capabilities; and inference refinement, in which the model improves its answers during runtime, without touching its parameters.
Data Science Ph.D. student Park said, "This survey helped us understand LLM self-improvement as a closed-loop process, where data acquisition, data selection, model optimization, and inference refinement work together to enable continuous improvement."
The framework stretched outward from the center. Most of the research the team studied was concerned with optimization alone, and optimization is not self-contained — it requires data, and it produces a model that then goes on being used. Extending backward and forward closed the circle. “It's a loop,” Yang said. “We were looking at the entire model development lifecycle. But we needed another layer to monitor this loop, to make sure the model improves in the right direction.” That became the fifth component: an autonomous ‘Evaluation’ layer placed above the cycle, determining whether the system is genuinely improving or merely appearing to improve.
The Evaluation layer plays a distinct role in the framework, addressing a challenge the field currently faces. Benchmarks wear out. A test that once separated capable models from weak ones eventually becomes easier for most models to pass, so researchers are prompted to continue building harder ones. This problem becomes even more pronounced for models undergoing continual self-modification, where fixed benchmarks quickly lose their ability to measure meaningful progress.
Zhou envisions a system that can instruct itself to become better at certain tasks such as handling engineering or medical knowledge, so that it automatically generates the tests needed to ensure it actually improves. “How do I know I’ve mastered Python? I need to take a test. In school, those tests are given by teachers. But in the real world, if I want to master something, I go and find the relevant test myself, so I know I’ve got there.”
On the other hand, the feedback loops that allow a model to improve itself can also magnify its mistakes. The risks can begin with the data. When models repeatedly learn from the outputs they have generated, diversity can shrink, errors can be recycled, and previously learned capabilities may be forgotten — eventually leading to what researchers call ‘model collapse.’ Park said, "Focusing on data selection in particular shows the importance of filtering and curating high-quality data from existing corpora, as the quality of training data plays a critical role in how effectively models improve."
The problem runs deeper still. Self-improving systems increasingly rely on models to evaluate their outputs, but those feedback signals can be biased, inconsistent, or unstable. Models may prefer their own responses, give contradictory judgments, or change their evaluations after small changes in wording. Once such imperfect feedback is used for training, the system can reinforce wrong behavior rather than correct it. “One example of this is reward hacking,” Yang said. “A model can learn to maximize the scoring metric it is given, instead of working toward the underlying objective that the score was originally meant to represent.”
Moreover, these technical weaknesses become more consequential, compounding risks as the systems grow more autonomous. A model that determines its own data, feedback, actions, and updates also becomes harder to oversee. In high-stakes settings such as medicine or finance, small mistakes can harm individuals or even propagate across an entire system. Greater autonomy can also create risks that go beyond ordinary model error, including unintended harmful actions, deliberate misuse, and behavior that becomes increasingly difficult for human or automated supervisors to detect and reverse.
Zhou sees identifying these potential risks as an important part of the work. “One of our purposes is to lay out as many of these challenges and safety concerns as possible. The goal is not to remove humans from the loop altogether, but to determine where autonomy is useful and where stronger safeguards are needed, so we can keep human oversight strongest when the consequences of failure are most detrimental.”
Self-improvement systems are already being explored across six domains of major applications surveyed in the paper: code, mathematics, healthcare, finance, science, and automated research. Code and mathematics remain especially well suited to self-improvement because they offer clear, verifiable feedback — a compiler can check whether code works, and a prover can verify mathematical results. In healthcare and finance, such signals are naturally harder to obtain.
The vision is an end-to-end self-improving system where humans define the goal and the system handles the model improvement process. Instead of requiring users to manage data collection, training, evaluation, and repeated optimization, the model would coordinate these steps autonomously and continue improving toward the target. A physician, for example, should not need to understand all the details of how the model is trained or improved for their specific application. “They should be able to hand the query or the requirement to the system,” Yang said, “and the system can handle everything accordingly.”
The team already started turning this vision into a working prototype through Zevo, an end-to-end self-improving system designed to automate the full model improvement process. Instead of requiring users to manually manage each stage of model development, Zevo starts with a user-defined objective and evaluation setup, then coordinates a group of specialized AI agents across data, training, inference, evaluation, infrastructure, and model management. The system proposes different ways to improve a model, evaluates each attempt against the user’s objective, keeps the best-performing version, and continues iterating.
“The broader goal is to move toward a future where improving an AI model becomes less like manually engineering every training decision and more like specifying what the model should become,” Yang said. Zevo is also designed with different levels of autonomy, allowing users to decide how much of the improvement process they want to control themselves and how much they want the system to handle autonomously.
Computer Science Master’s student Xerri said, “Our framework validates how practitioners are actually building the next generation of self-improving LLMs. What's most exciting is seeing the agentic tools we describe, like autonomous data acquisition, tool use, and closed-loop evaluation, move rapidly from research into real-world deployment across academia and even industry.”
Zhou sees their work as a blueprint. "This is a sci-fi moment,” he says, “But it's important that we study deeply at this stage, so that we can make sure we’re building a better future, and not the worse one."