NeurIPS 2020 - Thirty-fourth Conference on Neural Information Processing Systems - https://nips.cc/
Abstract: The landscape of machine learning evolves rapidly and the complexity of the networks and their architectures defies easy comprehension. AI is touted as the next scientific revolution by allowing the processing and pattern-finding in increasingly massive data sets. One potential end results could be AI enhanced measurement technologies, but what does that mean? This talk will give examples of how classical tools indicate the technical obstacles to this vision in terms of understanding training processes, model comparisons, and feature embeddings. While the results in this talk are largely empirical, they point to interesting directions for (infomation?) theoretical investigation.
Bio: Anand D. Sarwate is an Associate Professor in the Electrical and Computer Engineering Department at Rutgers, The State University of New Jersey. He received B.S. degrees in math and electrical engineering from MIT and a Ph.D. in electrical engineering from UC Berkeley. Prior to joining Rutgers he was a Research Assistant Professor at TTI-Chicago and a postdoc at the ITA Center at UC San Diego. His research interests include information theory, machine learning, signal processing, optimization, and privacy and security.
Location: Light Engineering 250
The Center of Excellence in Wireless and Information Technology (CEWIT) will host the 16th International Conference on Emerging Technologies for a Smarter World (CEWIT2020) virtually on November 5, 2020. The conference will center on the four major fields which are penetrating our business and personal lives: Machine Learning, Artificial Intelligence, Blockchain and Computational Medicine. For more info visit: https://www.cewit.org/.
Abstract: Many unresolved legal questions over LLMs and copyright center on memorization: whether specific training data have been encoded in the model's weights during training, and whether those memorized data can be extracted in the model's outputs. While many believe that LLMs do not memorize much of their training data, recent work shows that substantial amounts of copyrighted text can be extracted from open-weight models. However, it remains an open question if similar extraction is feasible for production LLMs, given the safety measures these systems implement. We investigate this question using a two-phase procedure: (1) an initial probe to test for extraction feasibility, which sometimes uses a Best-of-N (BoN) jailbreak, followed by (2) iterative continuation prompts to attempt to extract the book. We evaluate our procedure on four production LLMs -- Claude 3.7 Sonnet, GPT-4.1, Gemini 2.5 Pro, and Grok 3 -- and we measure extraction success with a score computed from a block-based approximation of longest common substring (nv-recall). With different per-LLM experimental configurations, we were able to extract varying amounts of text. For the Phase 1 probe, it was unnecessary to jailbreak Gemini 2.5 Pro and Grok 3 to extract text (e.g, nv-recall of 76.8% and 70.3%, respectively, for Harry Potter and the Sorcerer's Stone), while it was necessary for Claude 3.7 Sonnet and GPT-4.1. In some cases, jailbroken Claude 3.7 Sonnet outputs entire books near-verbatim (e.g., nv-recall=95.8%). GPT-4.1 requires significantly more BoN attempts (e.g., 20X), and eventually refuses to continue (e.g., nv-recall=4.0%). Taken together, our work highlights that, even with model- and system-level safeguards, extraction of (in-copyright) training data remains a risk for production LLMs.
Speaker: Xinyue
Location: CS2311
Speaker: Xinyue
Location: CS2311
Join Stony Brook University's Center for Excellence in Learning and Teaching (CELT) for a bootcamp on how to use AI to enhance your teaching and courses. This event will demonstrate how ChatGPT, Microsoft Copilot, and other generative AI platforms can support you in crafting learning objectives, writing exam questions, composing rubrics, and designing course content such as lesson plans, in-class activities, instructional videos, and more.
Register here.
Register here.
Are you concerned about AI issues with your asynchronous online courses? Is your fully online course vulnerable to AI plagiarism? Do you want to engage your online students using AI? Discover the future of education with our AI-powered solutions designed specifically for online asynchronous courses. This innovative approach uses artificial intelligence to transform the way courses are delivered, making learning more personalized, engaging, and effective.
Register here: https://stonybrook.zoom.us/meeting/register/RD94cHiHRwCj6xNkCZqNEg
Register here: https://stonybrook.zoom.us/meeting/register/RD94cHiHRwCj6xNkCZqNEg
The overall purpose of this seminar is to bring together people with interests in Computer Vision theory and techniques and to examine current research issues. This course will be appropriate for people who already took a Computer Vision graduate course or already had research experience in Computer Vision. To enroll in this course, you must either: (1) be in the PhD program or (2) receive permission from the instructors.
Each seminar will consist of multiple short talks (around 10 minutes) by multiple people. Students can register for 1 credit for CSE 656. Registered students must attend and present a minimum of 2 or 3 talks. Everyone else is welcome to attend. Fill in https://forms.gle/pCVXovgfMfQwGqG38 to subscribe to our mailing list for further announcement.
Each seminar will consist of multiple short talks (around 10 minutes) by multiple people. Students can register for 1 credit for CSE 656. Registered students must attend and present a minimum of 2 or 3 talks. Everyone else is welcome to attend. Fill in https://forms.gle/pCVXovgfMfQwGqG38 to subscribe to our mailing list for further announcement.
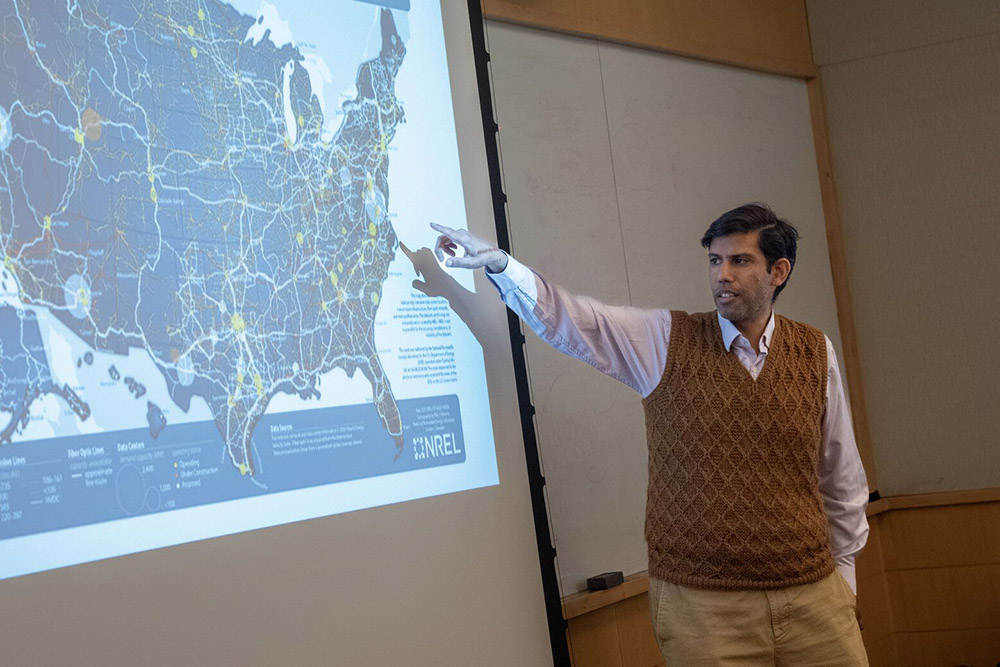
Artificial intelligence transforms daily life a little more every day. Healthcare, business, science, the arts, and every other discipline are facing new ethical and environmental challenges as they grapple with the new capabilities and possibilities that come with artificial intelligence.
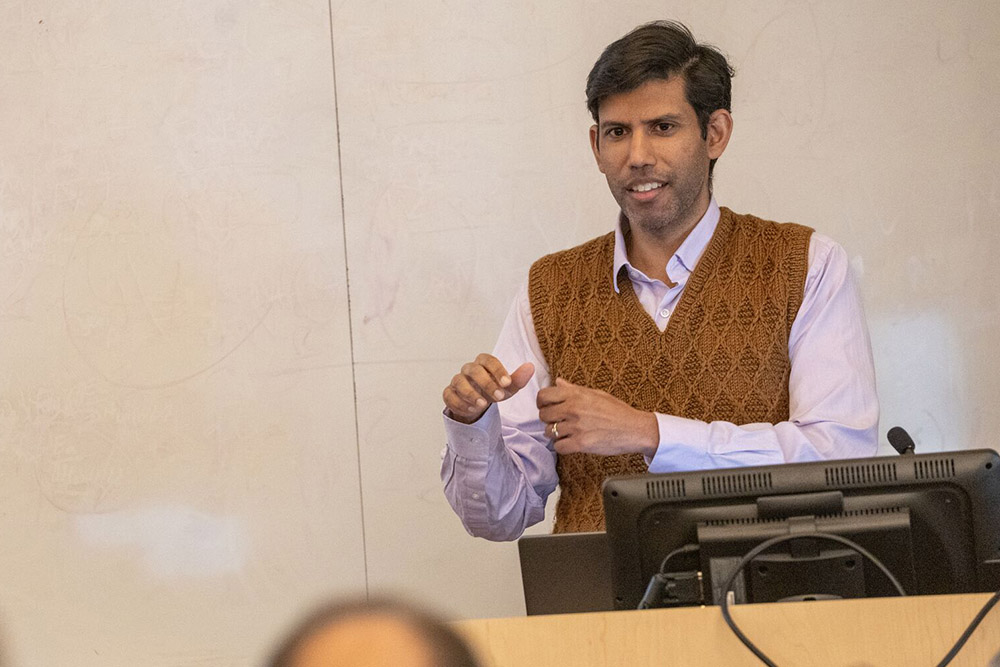
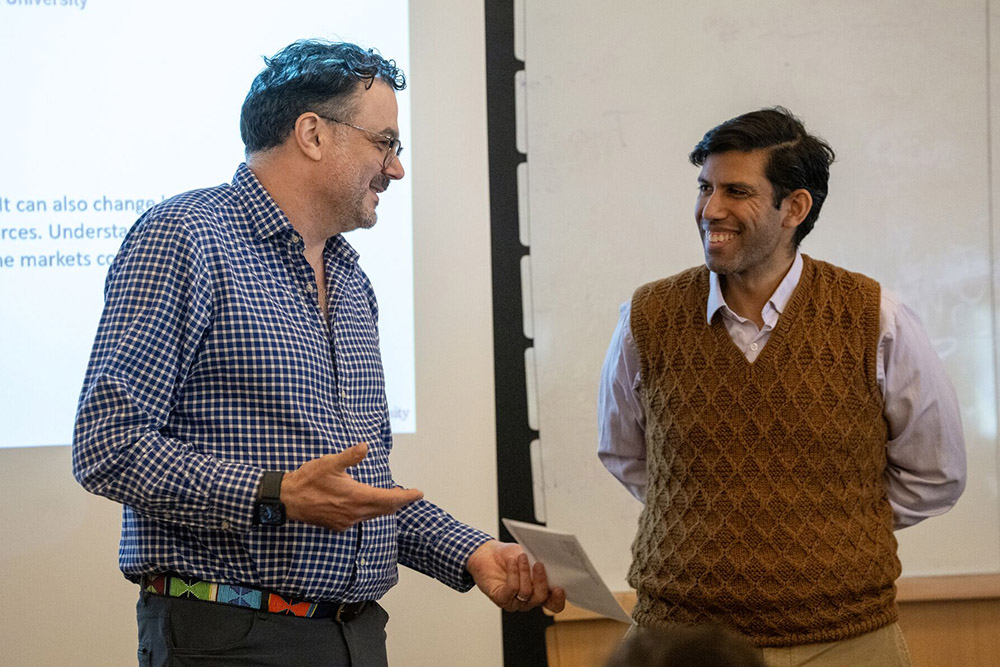
In a far-reaching discussion titled “The Physical Economy of Intelligence: Marketcraft, Data Centers and Climate,” Lav Varshney, Della Pietra Infinity Professor and Inaugural Director of Stony Brook University’s AI Innovation Institute, discussed the puzzles, pitfalls and possibilities of an increasingly AI-reliant world.
In a State of the University Address on September 14 at the Staller Center, the second-year president, who is an engineer by training, suggested that the university embrace the opportunities presented by the latest technologies, preparing students for life after college and creating opportunities across Long Island.
New research, certified by the Transactions on Machine Learning Research journal, presents a comprehensive framework for how large language models can increasingly improve themselves.
Stony Brook, NY, September 22, 2026 - Human expertise and engineering have played a central role in shaping the large language models we use today. People wrote training examples, ranked model responses, corrected errors, and provided the knowledge and judgment needed to guide model development.